Five Lessons From the First Three Years of Michelangelo

Five Lessons From the First Three Years of Michelangelo

  • November 14, 2018
Table of Contents

Five Lessons From the First Three Years of Michelangelo

Uber has been one of the most active contributors to open source machine learning technologies in the last few years. While companies like Google or Facebook have focused their contributions in new deep learning stacks like TensorFlow, Caffe2 or PyTorch, the Uber engineering team has really focused on tools and best practices for building machine learning at scale in the real world. Technologies such as Michelangelo, Horovod, PyML, Pyro are some of examples of Uber’s contributions to the machine learning ecosystem.

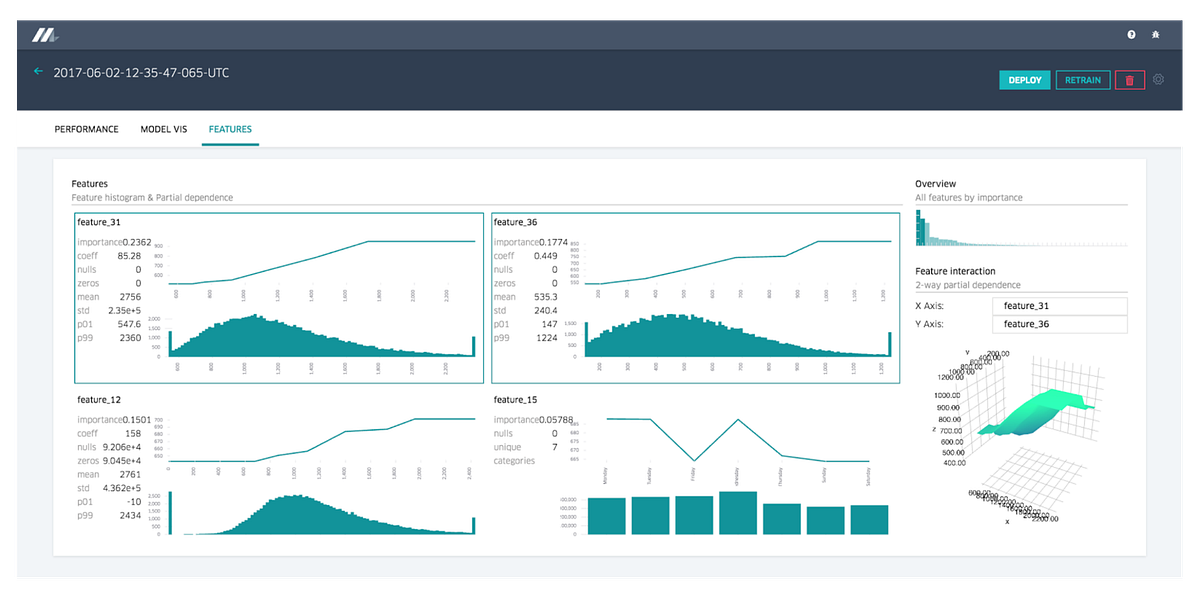
With only a small group of companies developing large scale machine learning solutions, the lessons and guidance from Uber becomes even more valuable for machine learning practitioners (I certainly learned a lot and have regularly written about Uber’s efforts). Recently, the Uber engineering team published an evaluation of the first three years of operations of the Michelangelo platform. If we remove all the Michelangelo specifics, Uber’s post contains a few non-obvious, valuable lessons for organizations starting in their machine learning journey.

I am going to try to summarize some of those key takeaways in a more generic way that can be applicable to any mainstream machine learning scenario.

Source: towardsdatascience.com

Tags :
Share :
comments powered by Disqus

Related Posts

A Google Brain engineer’s guide to entering AI

A Google Brain engineer’s guide to entering AI

Note that this guide was written in November 2018 to complement an in-depth conversation on the 80,000 Hours Podcast with Catherine Olsson and Daniel Ziegler on how to transition from computer science and software engineering in general into ML engineering, with a focus on alignment and safety. If you like this guide, we’d strongly encourage you to check out the podcast episode where we discuss some of the instructions here, and other relevant advice. Technical AI safety is a multifaceted area of research, with many sub-questions in areas such as reward learning, robustness, and interpretability.

Read More
Why Chinese Artificial Intelligence Will Run The World

Why Chinese Artificial Intelligence Will Run The World

With Chinese tech giants Baidu, Alibaba, and Tencent focused on developing sophisticated AI-driven systems in the coming decade, the rest of the world can only watch while China builds the computer systems that will run our world in the decades to come. If you’ve been paying attention in the past year, it seems that all anyone can talk about is the coming artificial intelligence boom on the horizon. Whether it’s the Amazon, Google, or Facebook, everyone seems to be getting in on the AI game as fast as they can.

Read More
Tensorflow 2.0: models migration and new design

Tensorflow 2.0: models migration and new design

Tensorflow 2.0 will be a major milestone for the most popular machine learning framework: lots of changes are coming, and all with the aim of making ML accessible to everyone. These changes, however, requires for the old users to completely re-learn how to use the framework: this article describes all the (known) differences between the 1.x and 2.x version, focusing on the change of mindset required and highlighting the pros and cons of the new and implementations. This article can be a good starting point also for the novice: start thinking in the Tensorflow 2.0 way right now, so you don’t have to re-learn a new framework (unless until Tensorflow 3.0 will be released).

Read More